 Jack
6991e76632
### What problem does this PR solve?

Issue Number: None

Related PR: #69052

Problem Summary: score() of pattern queries disagrees with Elasticsearch
and with itself:

    -- 'Inverted indexes are suitable for full text search',
    -- 'The parser splits text into multiple terms', ...
SELECT score() FROM document WHERE SEARCH('content:/.*ext/'); -- BM25
sum
SELECT score() FROM document WHERE SEARCH('content:*ext'); -- BM25 sum
    SELECT score() FROM document WHERE SEARCH('content:te*');      -- 1
    SELECT score() FROM document WHERE content MATCH_REGEXP 'ext'; -- 0

Elasticsearch scores a query_string /regexp/, wildcard or prefix, and a
regexp, wildcard or prefix query, with a constant 1 per matching row
(default rewrite constant_score_blended); measured on 9.5.5 with the
rows above: 1.0 for both matching rows. Only an explicit
"rewrite": "scoring_boolean" sums the BM25 of the expanded terms. Next
to a scored clause in a bool must, a regexp adds exactly 1.

#69052 made SEARCH regexp and wildcard sum the BM25 of every expanded
term, i.e. scoring_boolean always on, while prefix stayed constant. That
sum also takes idf and avgdl from the current segment, not from the
tablet statistics MATCH uses: two inserts of the same text scored
0.2876821 and 1.3862942 for identical 'apple' rows, while MATCH 'apple'
scored 0.6931471 for both. MATCH_REGEXP never requested a scoring
context, so it scored 0 like a filter.

Fix:
1. Revert the scoring part of #69052: ExpandWeight scores every pattern
   with the constant scorer again. The test fixture extensions that
   #69051 built on are kept.
2. MATCH_REGEXP requests scoring on every index; the regexp expansion
   then publishes the constant 1. The MATCH statistics collector skips
   it, since a constant reads no statistics and the pattern is not text
   to analyze.
🌍 Read this in other language
English • العربية • বাংলা • Deutsch • Español • فارسی • Français • हिन्दी • Bahasa Indonesia • Italiano • 日本語 • 한국어 • Polski • Português • Română • Русский • Slovenščina • ไทย • Türkçe • Українська • Tiếng Việt • 简体中文 • 繁體中文





Apache Doris is an open-source, real-time analytics and search database built on MPP architecture. It provides fast SQL analytics, lakehouse query acceleration, and hybrid search across structured, text, and vector data.
Explore the official website for the latest product overview, use cases, ecosystem updates, blogs, and user stories. For version updates, see all release notes.
📈 Use Cases
| Use Case | What it provides |
|---|---|
| Customer-Facing Analytics | Ship sub-second interactive analytics to external users. |
| Data Warehousing | Build one real-time warehouse across business domains. |
| Observability | Analyze high-throughput logs, events, and metrics with SQL. |
| Doris for AI | Use vector, text, JSON, and structured search in one SQL engine. |
🚀 Core Capabilities
Apache Doris is built around three core capabilities. The website is the source of truth for detailed product descriptions and examples.
| Capability | What it provides |
|---|---|
| Real-Time Analytics | Streaming ingestion, incremental transformation, and sub-second queries under high concurrency. |
| Lakehouse Analytics | Fast SQL analytics over open table formats such as Iceberg, Delta Lake, and Hudi. |
| Hybrid Search | SQL-native analytics across JSON, full-text, and vector data for AI and search workloads. |
🔌 Ecosystem
Doris sits at the center of the modern data stack. It connects upstream databases, streaming systems, and lakehouse storage with downstream BI, AI, analytics, and observability tools.

For the latest ecosystem coverage, visit the official website and the connection and integration documentation.
👣 Get Started
🧱 Architecture
Apache Doris supports both compute-storage coupled and compute-storage decoupled deployments. In decoupled mode, stateless compute groups run over shared object storage, so you can scale compute on demand and isolate workloads.
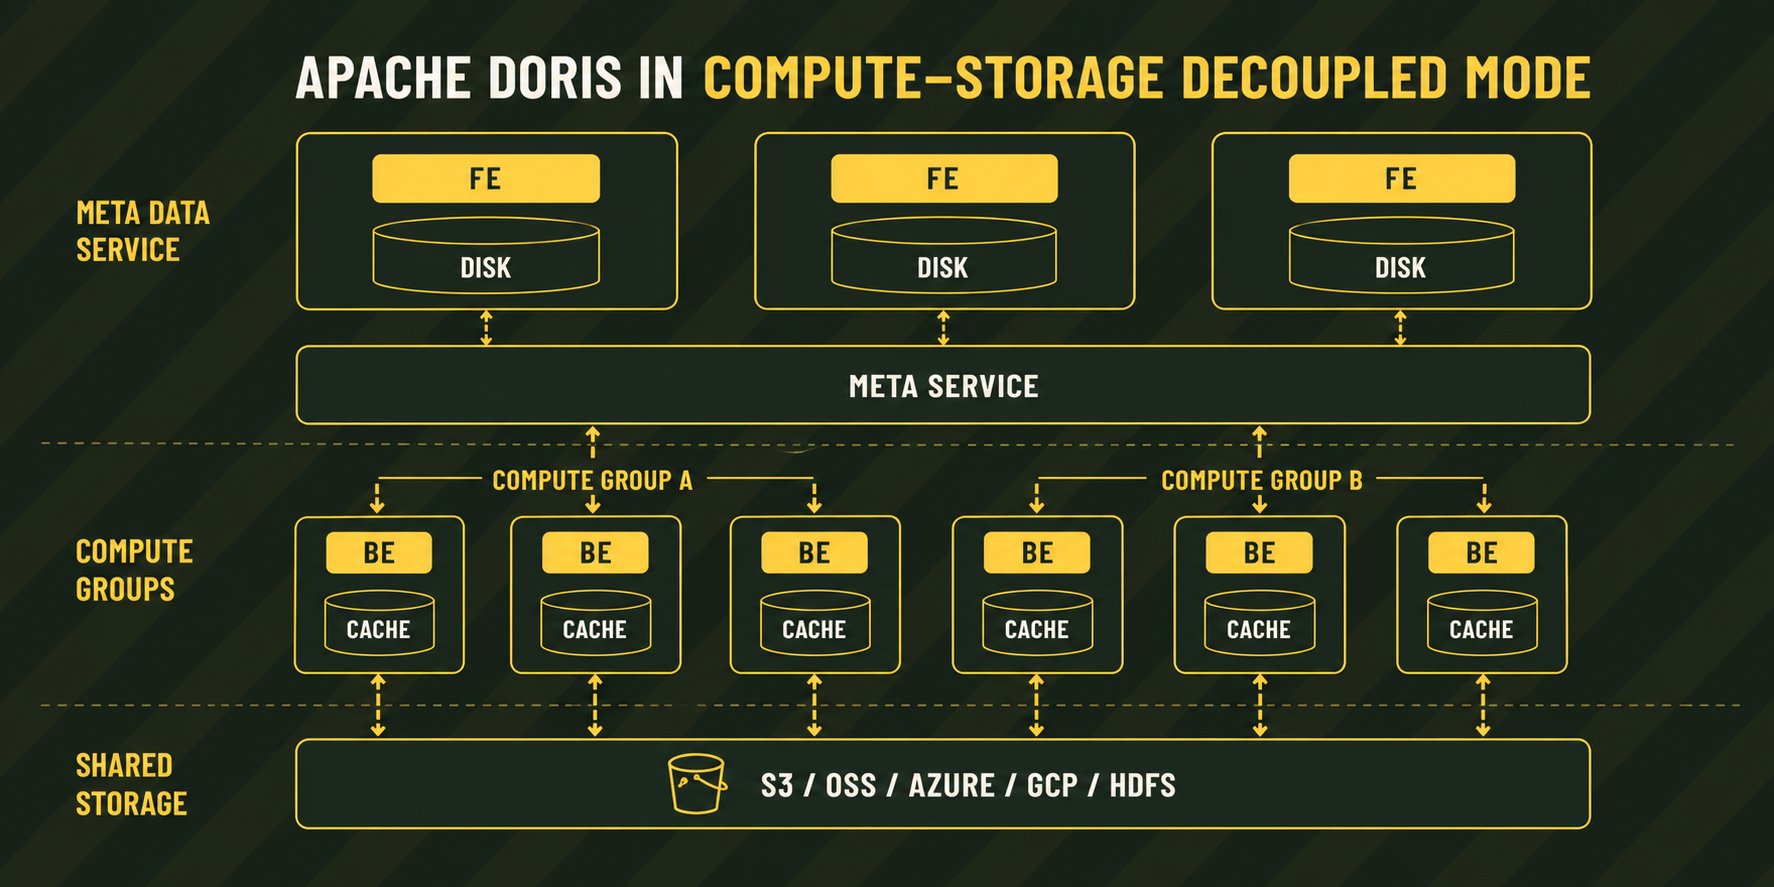
Learn more in the deployment guide and deployment mode guide.
📣 Project Updates
| Resource | What it provides |
|---|---|
| Community Report | Weekly updates on community activity, merged PRs, contributors, and feature progress. |
| Roadmap 2026 | The 2026 planning discussion for AI and hybrid search, query engine, storage, and data lake work. |
🧩 Components
Doris provides connectors and tools for common data engineering workflows.
- Doris Flink Connector
- Doris Spark Connector
- Doris Kafka Connector
- Doris Stream Loader
- Doris Kubernetes Operator
👨👩👧👦 Users
Apache Doris is used in production by thousands of companies worldwide across internet services, finance, retail, logistics, manufacturing, energy, telecommunications, AI, and other industries.
🙌 Contributors
Apache Doris graduated from the Apache Incubator and became an Apache Top-Level Project in June 2022. Thanks to all community contributors who help build Doris.
🌈 Community and Support
💬 Contact Us
🧰 Links
- Apache Doris official website: doris.apache.org
- X: @doris_apache
- Medium: @ApacheDoris
📜 License
Note
Some licenses of the third-party dependencies are not compatible with Apache 2.0 License. So you need to disable some Doris features to comply with Apache 2.0 License. For details, refer to the
thirdparty/LICENSE.txt