 zy-kkk
da03ee7824
### What problem does this PR solve?

Issue Number: close #68625

Related PR: #68453 (time travel, tags, branches and managed versioning
for Lance table scans)

Problem Summary:

`vector_search()` and `full_text_search()` always searched the latest
version of `main`, and their `table` argument rejected `FOR VERSION AS
OF`, `@tag` and `@branch`. A search could not be reproduced against a
released tag, compared across versions, or run on an experimental
branch.

Both TVFs now take four optional properties, with the semantics of the
table syntax from #68453:

| Property | Value | Table syntax | Combines with |
|-|-|-|-|
| `version` | positive integer | `FOR VERSION AS OF N` | `branch` |
| `timestamp` | `yyyy-MM-dd HH:mm:ss[.SSS]`, session time zone | `FOR
TIME AS OF` | `branch` |
| `tag` | tag name | `@tag(name)` | none |
| `branch` | branch name, `main` is the main chain | `@branch(name)` |
`version` or `timestamp` |

```sql
SELECT id, _distance FROM vector_search(
    "table" = "lance_catalog.db.documents", "column" = "embedding",
    "query_vector" = "[0.1, 0.2, 0.3]", "version" = "3")
ORDER BY _distance;

SELECT id, _score FROM full_text_search(
    "table" = "lance_catalog.db.documents", "column" = "content", "query" = "database",
    "branch" = "dev", "timestamp" = "2026-09-20 12:00:00")
ORDER BY _score DESC;
```

How it works:

- **FE.** The TVF parses the properties into a `LanceRefSelector` and
loads its metadata through the same
`LanceCatalogClient.readTableSnapshot` as table scans, so
storage-versioned and namespace-managed tables follow the #68453 rules
unchanged. Schema, search column and field id, vector type and
dimension, fragments and index segments all come from the selected
snapshot, and planning never reopens the dataset. The splits carry the
branch directory URI and the version, so no thrift change is needed.
- **Each execution resolves again.** A bound TVF is never cached,
prepared statements re-analyze on every `EXECUTE`, and TVF statements
skip the SQL cache, so the latest version, a future time, a branch head
and a moved tag are resolved per execution and stay fixed within its
plan. `CREATE TABLE AS SELECT` plans its query twice (schema, then
rows), so there a moving selector can resolve twice, as it already can
for a table scan with an explicit selector; pinning `version` gives an
exact copy. This is documented.
- **No fallback.** A snapshot that cannot be selected, or whose index
files are missing, is an error; nothing falls back to the latest
version.
- **EXPLAIN** of a search node now shows `lanceCatalogType`,
`lanceManagedVersioning` and `lanceBranch` next to `lanceVersion`, as
table scans do. Planner errors that name "dataset version N" also name
the branch, since branch versions overlap main's.

Decisions worth calling out:

- `version` takes only a number. `FOR VERSION AS OF 'x'` names a tag
because SQL has one clause for both; the TVF has a `tag` property, and
Lance allows tag names made of digits, which `FOR VERSION AS OF` cannot
reach.
- An empty selector value is an error rather than "not set", so an empty
client-side variable cannot silently search the latest version of
`main`.
- The selector properties must be constants. Accepting `?` would leave
PREPARE without a snapshot to take the result schema from.
`full_text_search` now rejects `?` in any property: until now a
placeholder reached it as the literal text "?", so `'query'=?` searched
for "?".
- Each search relation resolves its own snapshot, as each explicit
selector already does for table scans. `vector_search(t) JOIN t` can
read two versions if a commit lands in between; pinning both with
`version` / `FOR VERSION AS OF` avoids that. This is documented.
- A managed table's branch is opened by a URI Doris joins
(`<table>/tree/<branch>`), which Lance does not validate on that path,
so Doris now rejects names that could leave the table's `tree/`
directory or change that URI: empty segments, `..`, `\`, and ASCII
characters other than letters, digits, `.`, `-`, `_` and `/`, so
`../other` and a percent-encoded dot segment are rejected before the
branch is opened. Outside ASCII only whitespace and control characters
are rejected, so no name Lance accepts is rejected, whichever Unicode
version the JDK and Lance's Rust use. Other tables check a branch out
through Lance, which validates the name itself.

BE changes:

- A search split or a two-phase row fetch without a positive version is
rejected instead of opening the latest version.
- Errors from opening the dataset, reading batches, preparing the FTS
query context and the two-phase row fetch name the snapshot: "... at
Lance dataset version N at <uri>", with the query string and any
password removed from the URI. Missing index files surface at execution
because Lance loads indexes lazily.
- Fragment ids from the FE must exist in the opened snapshot. lance-c
silently skips unknown fragment ids, which would drop rows without an
error.
- The profile records `LanceDatasetVersion` and `LanceDatasetUri`, the
snapshot an execution actually read. EXPLAIN cannot show this for moving
selectors because it resolves again.
- **Behavior change for every vector search:** a split without index
segments now always runs flat (`use_index=false`). The FE plans such
splits as flat search, and EXPLAIN and the profile count them as flat,
but Lance used to search them with the first index on the column in
manifest order, which need not be the index the FE selected (for example
while an index is rebuilt under a new name). Indexes the FE cannot plan
with (no fragment coverage metadata, no recorded metric, or a legacy
index whose details Lance cannot infer from its files, which the FE
skips; `lanceVectorIndexStatus=UNKNOWN_COVERAGE` / `METRIC_MISMATCH` /
`NO_MATCH`) are therefore no longer used implicitly, and such searches
become exact flat searches. Results can change only where the unplanned
index was approximate; latency can grow on such datasets. Legacy indexes
that lack details but whose details Lance infers, such as those written
by Lance 0.10 to 0.24, are planned and searched as before
(`test_lance_vector_search_legacy_index`).
- A vector split that carries index segments while the request says
`use_index=false` is rejected. The FE plans segments only when
`use_index` allows them, so it never sends such a split; the BE now
takes `use_index` from the segments and would otherwise have to override
either the plan or the request.

Known limitations (documented):

- A branch of a branch, or a branch of a shallow clone, can fail to find
the index files it inherited, because Lance writers before v13 record
them under the intermediate branch (lance-format/lance#9176). The search
fails with an error.
- After a branch is deleted and recreated under the same name, or a
dataset is replaced at the same URI, version numbers repeat. Since
#68615 the BE's Lance keys the index list and the row-id index by the
manifest e_tag (lance-format/lance#8904, #8930), but the BE's
process-wide Lance session still keys two entries by version alone,
until eviction or restart. On datasets with stable row ids, the live-row
mask that vector and full-text search prefilter with can come from the
old data, so rows deleted in the new data can reappear or live rows can
be missing (lance-format/lance#9079, open). For a manifest without an
e_tag (V1 naming, or a store that returns no ETag), the index list can
come from the old data, on the BE and in the FE's Lance session until
the catalog is refreshed. Neither is introduced by this PR.
- `SHOW INDEX` and `lance_index_entries()` keep showing the latest
version of `main`.

### Release note

`vector_search()` and `full_text_search()` accept `version`,
`timestamp`, `tag` and `branch` to search a historical version, the
version at a time, a tag or a branch of a Lance table, including REST
Namespace managed tables. Vector search no longer uses an index the
planner did not select, and `full_text_search()` rejects
prepared-statement placeholders.

### Check List (For Author)

- Test: Regression test / Unit Test
- Regression: `external_table_p0/lance/test_lance_search_snapshot`
(filesystem catalog) and `test_lance_rest_search_snapshot` (REST,
storage-versioned and managed) on a new fixture `search_snapshot.lance`.
It has seven versions (appends, a vector index, an FTS index, an append
no index covers, a delete, a vector index rebuild), a tag, and a branch
`dev` whose versions and fragment ids overlap main's with different
rows, plus a tag at a non-latest branch version.
`search_snapshot_pruned.lance` lost a version to cleanup and the index
files of a tagged version. `search_snapshot_evolved.lance` adds a column
and renames the vector column after its index is built, then appends
data the index does not cover. The suites check rows, distances,
two-phase reads (on a branch, a tag, the columns of a version before and
after a rename, and a managed table through REST), EXPLAIN, full-text
search across a delete, `use_index=false` with a selector, every
selector error, and a managed branch named with a Unicode 16 letter
(`unicode_branch.lance`, built by pylance 12.0.0) through a table scan,
a search and a two-phase read. `test_lance_rest_catalog.out` and
`test_lance_rest_time_travel.out` list the new REST tables.
`test_lance_vector_search_legacy_index` searches a vector index written
by pylance 0.18.2 without index details and checks that it is planned
(`USED`, one segment) and returns the flat search's rows. All 30 suites
in `external_table_p0/lance` pass locally.
- FE unit tests: `LanceSearchSelectorTest` (property rules, time zones,
selector forwarding), `LancePreparedSearchTest` (both TVFs pass their
selector to the table; each analysis resolves it exactly once, and a
moved tag is resolved again on the next `EXECUTE`; search statements
bypass the SQL cache; placeholders rejected), `LanceScanNodeTest`
(EXPLAIN, errors naming the branch), `LanceCatalogClientTest` (branch
names, including letters newer than JDK 17's Unicode tables), and, with
real datasets and locally only like the other JNI tests,
`LanceSearchSnapshotTest` (historical index coverage, branches, tags,
schema evolution, cleanup, a snapshot planned before later commits) and
`LanceManagedVersioningTest` (managed versions, tags, branches,
unfinalized heads through the search entry points).
- BE unit tests in `lance_reader_test.cpp`: missing fragment ids on
normal, vector and FTS splits, unpinned versions, error and profile
contents, a split without index segments searching flat although an
index covers it, and a split with index segments under `use_index=false`
being rejected. The indexed variants of the existing multi-vector tests
now pass the index segments the FE would plan.
- Behavior changed: Yes. New TVF properties; vector splits without index
segments always search flat; `full_text_search` rejects `?`; managed
branch names are validated; the error for a time in removed history now
reads "Lance cannot select the version at or before '...'" instead of
"Lance cannot resolve FOR TIME AS OF '...'", because the TVF reaches it
too; BE errors name the dataset version and URI.
- Does this need documentation: Yes (apache/doris-website#4185)



Apache Doris is an easy-to-use, high-performance and real-time analytical database based on MPP architecture, known for its extreme speed and ease of use. It only requires a sub-second response time to return query results under massive data and can support not only high-concurrency point query scenarios but also high-throughput complex analysis scenarios.
All this makes Apache Doris an ideal tool for scenarios including report analysis, ad-hoc query, unified data warehouse, and data lake query acceleration. On Apache Doris, users can build various applications, such as user behavior analysis, AB test platform, log retrieval analysis, user portrait analysis, and order analysis.
🎉 Check out the 🔗All releases, where you'll find a chronological summary of Apache Doris versions released over the past year.
👀 Explore the 🔗Official Website to discover Apache Doris's core features, blogs, and user cases in detail.
📈 Usage Scenarios
As shown in the figure below, after various data integration and processing, the data sources are usually stored in the real-time data warehouse Apache Doris and the offline data lake or data warehouse (in Apache Hive, Apache Iceberg or Apache Hudi).
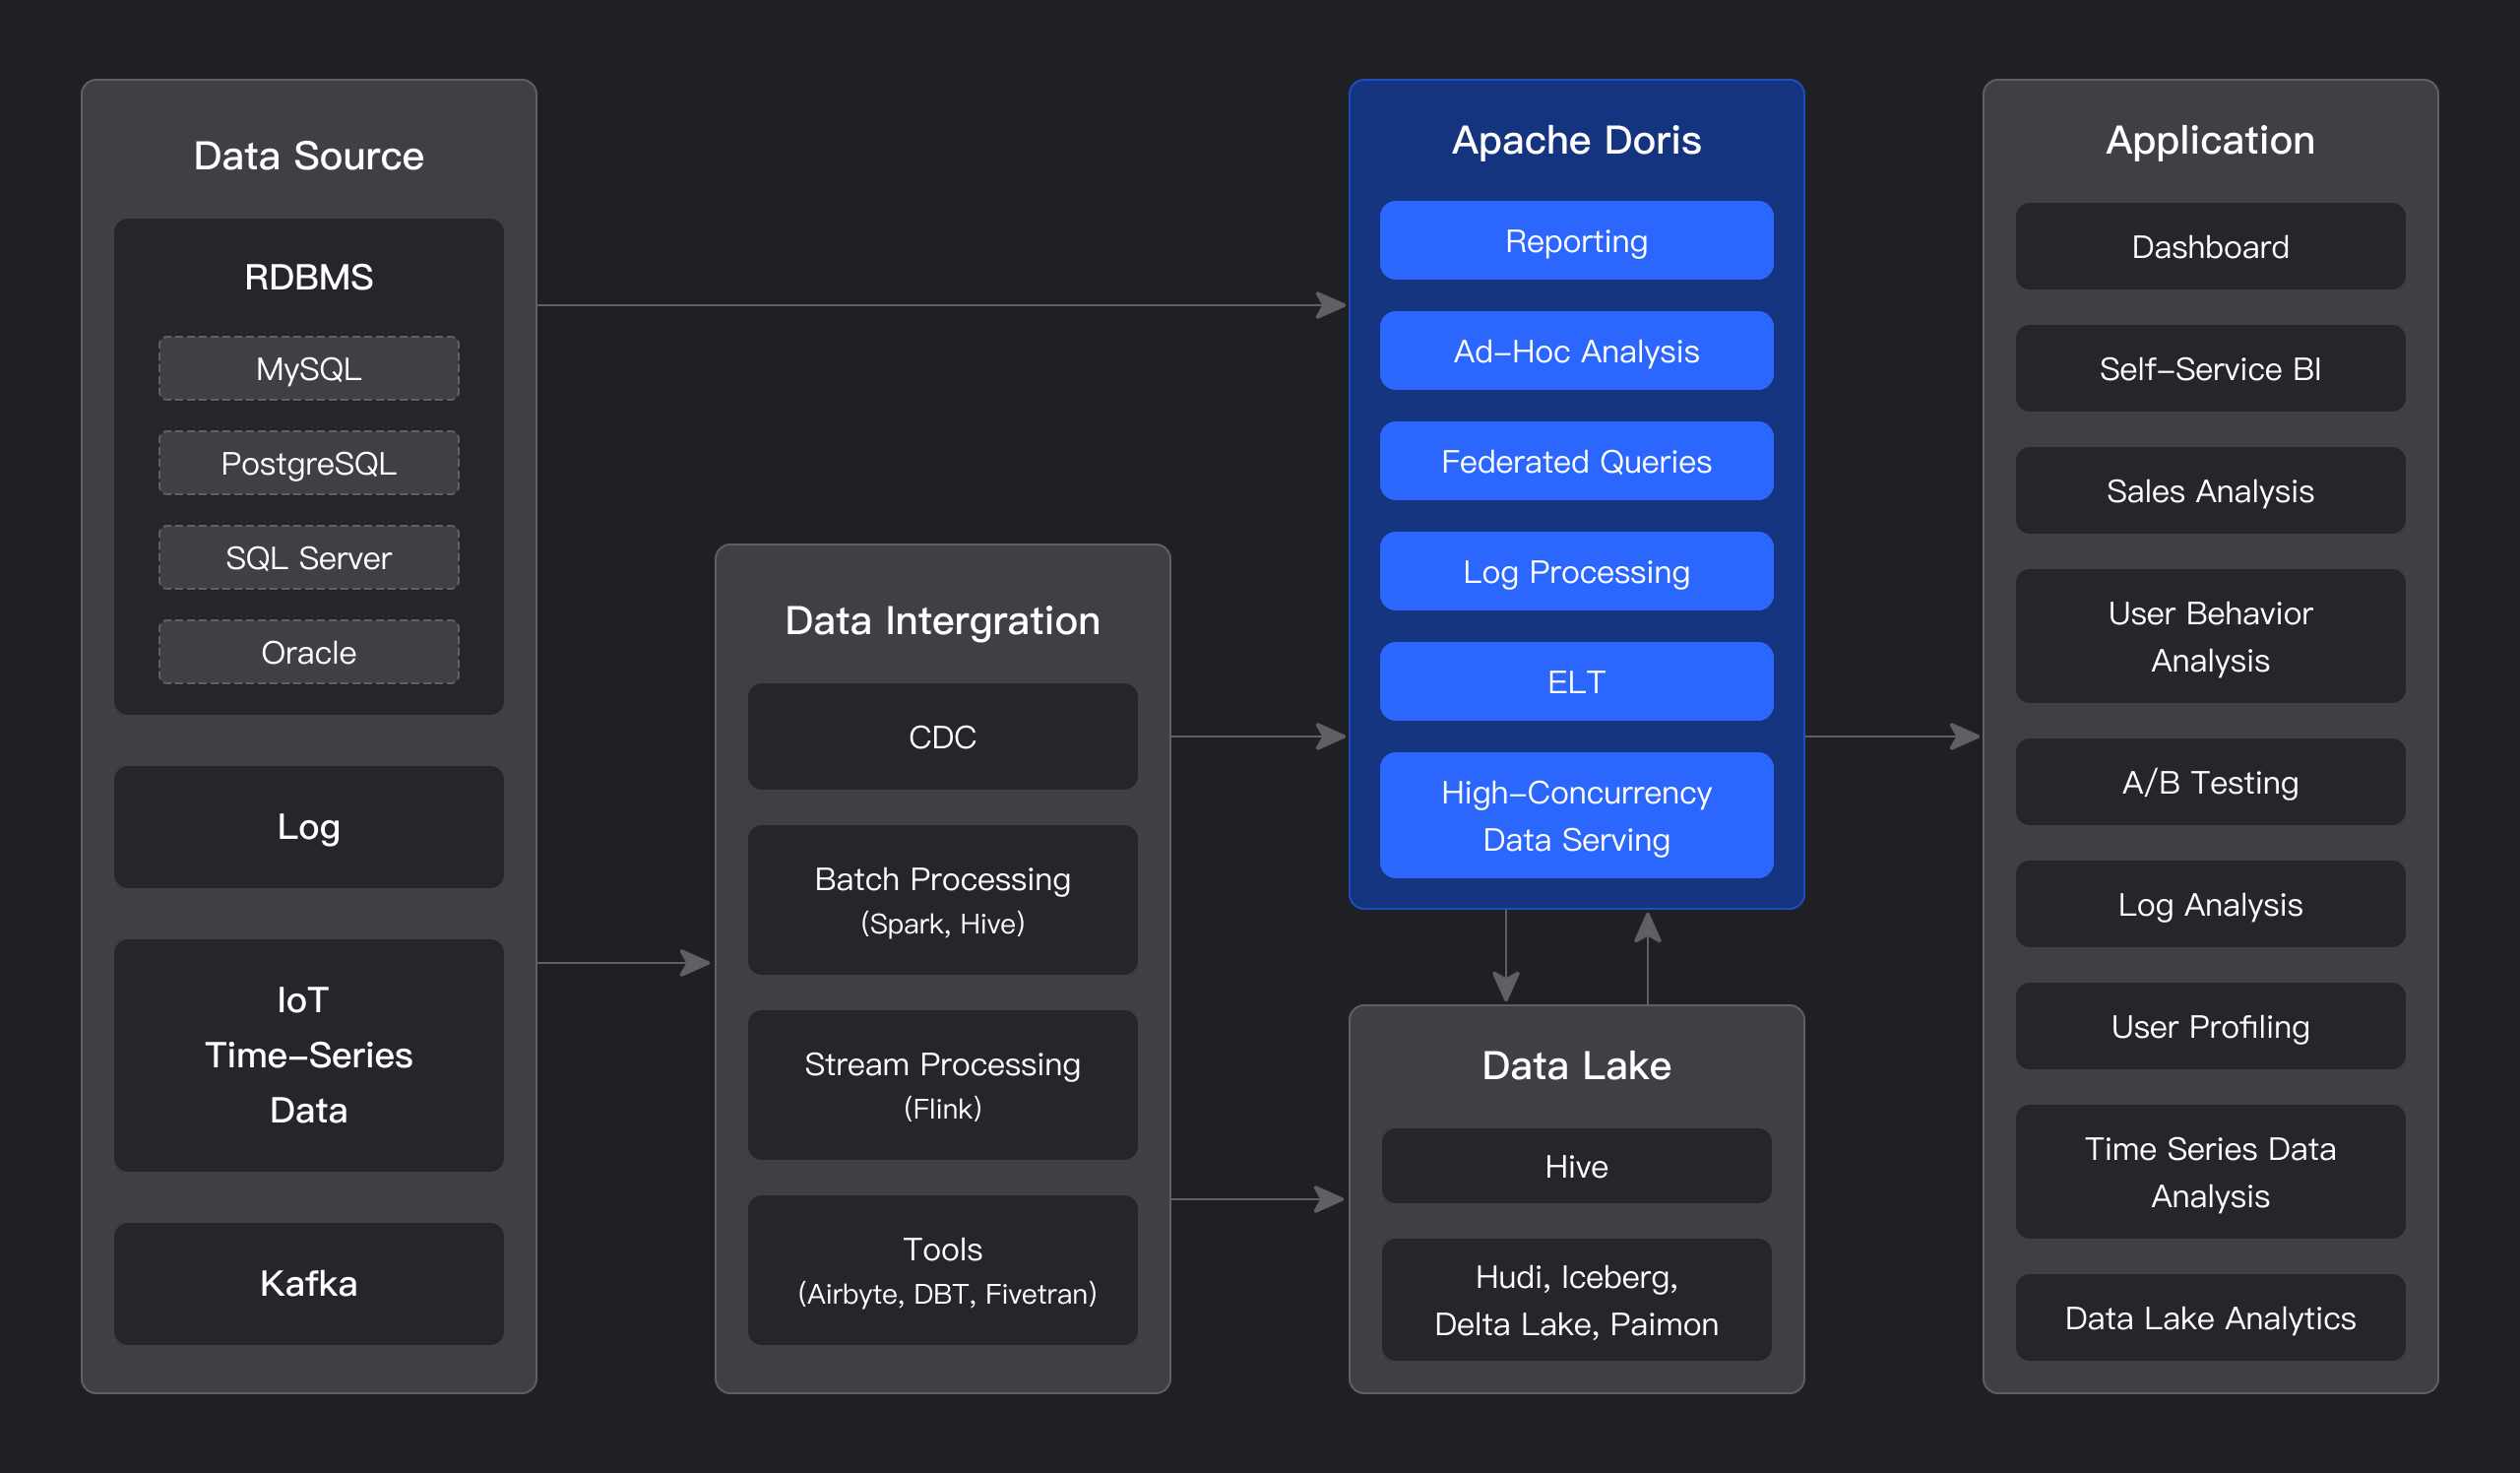
Apache Doris is widely used in the following scenarios:
-
Real-time Data Analysis:
-
Real-time Reporting and Decision-making: Doris provides real-time updated reports and dashboards for both internal and external enterprise use, supporting real-time decision-making in automated processes.
-
Ad Hoc Analysis: Doris offers multidimensional data analysis capabilities, enabling rapid business intelligence analysis and ad hoc queries to help users quickly uncover insights from complex data.
-
User Profiling and Behavior Analysis: Doris can analyze user behaviors such as participation, retention, and conversion, while also supporting scenarios like population insights and crowd selection for behavior analysis.
-
-
Lakehouse Analytics:
-
Lakehouse Query Acceleration: Doris accelerates lakehouse data queries with its efficient query engine.
-
Federated Analytics: Doris supports federated queries across multiple data sources, simplifying architecture and eliminating data silos.
-
Real-time Data Processing: Doris combines real-time data streams and batch data processing capabilities to meet the needs of high concurrency and low-latency complex business requirements.
-
-
SQL-based Observability:
- Log and Event Analysis: Doris enables real-time or batch analysis of logs and events in distributed systems, helping to identify issues and optimize performance.
Overall Architecture
Apache Doris uses the MySQL protocol, is highly compatible with MySQL syntax, and supports standard SQL. Users can access Apache Doris through various client tools, and it seamlessly integrates with BI tools.
Storage-Compute Integrated Architecture
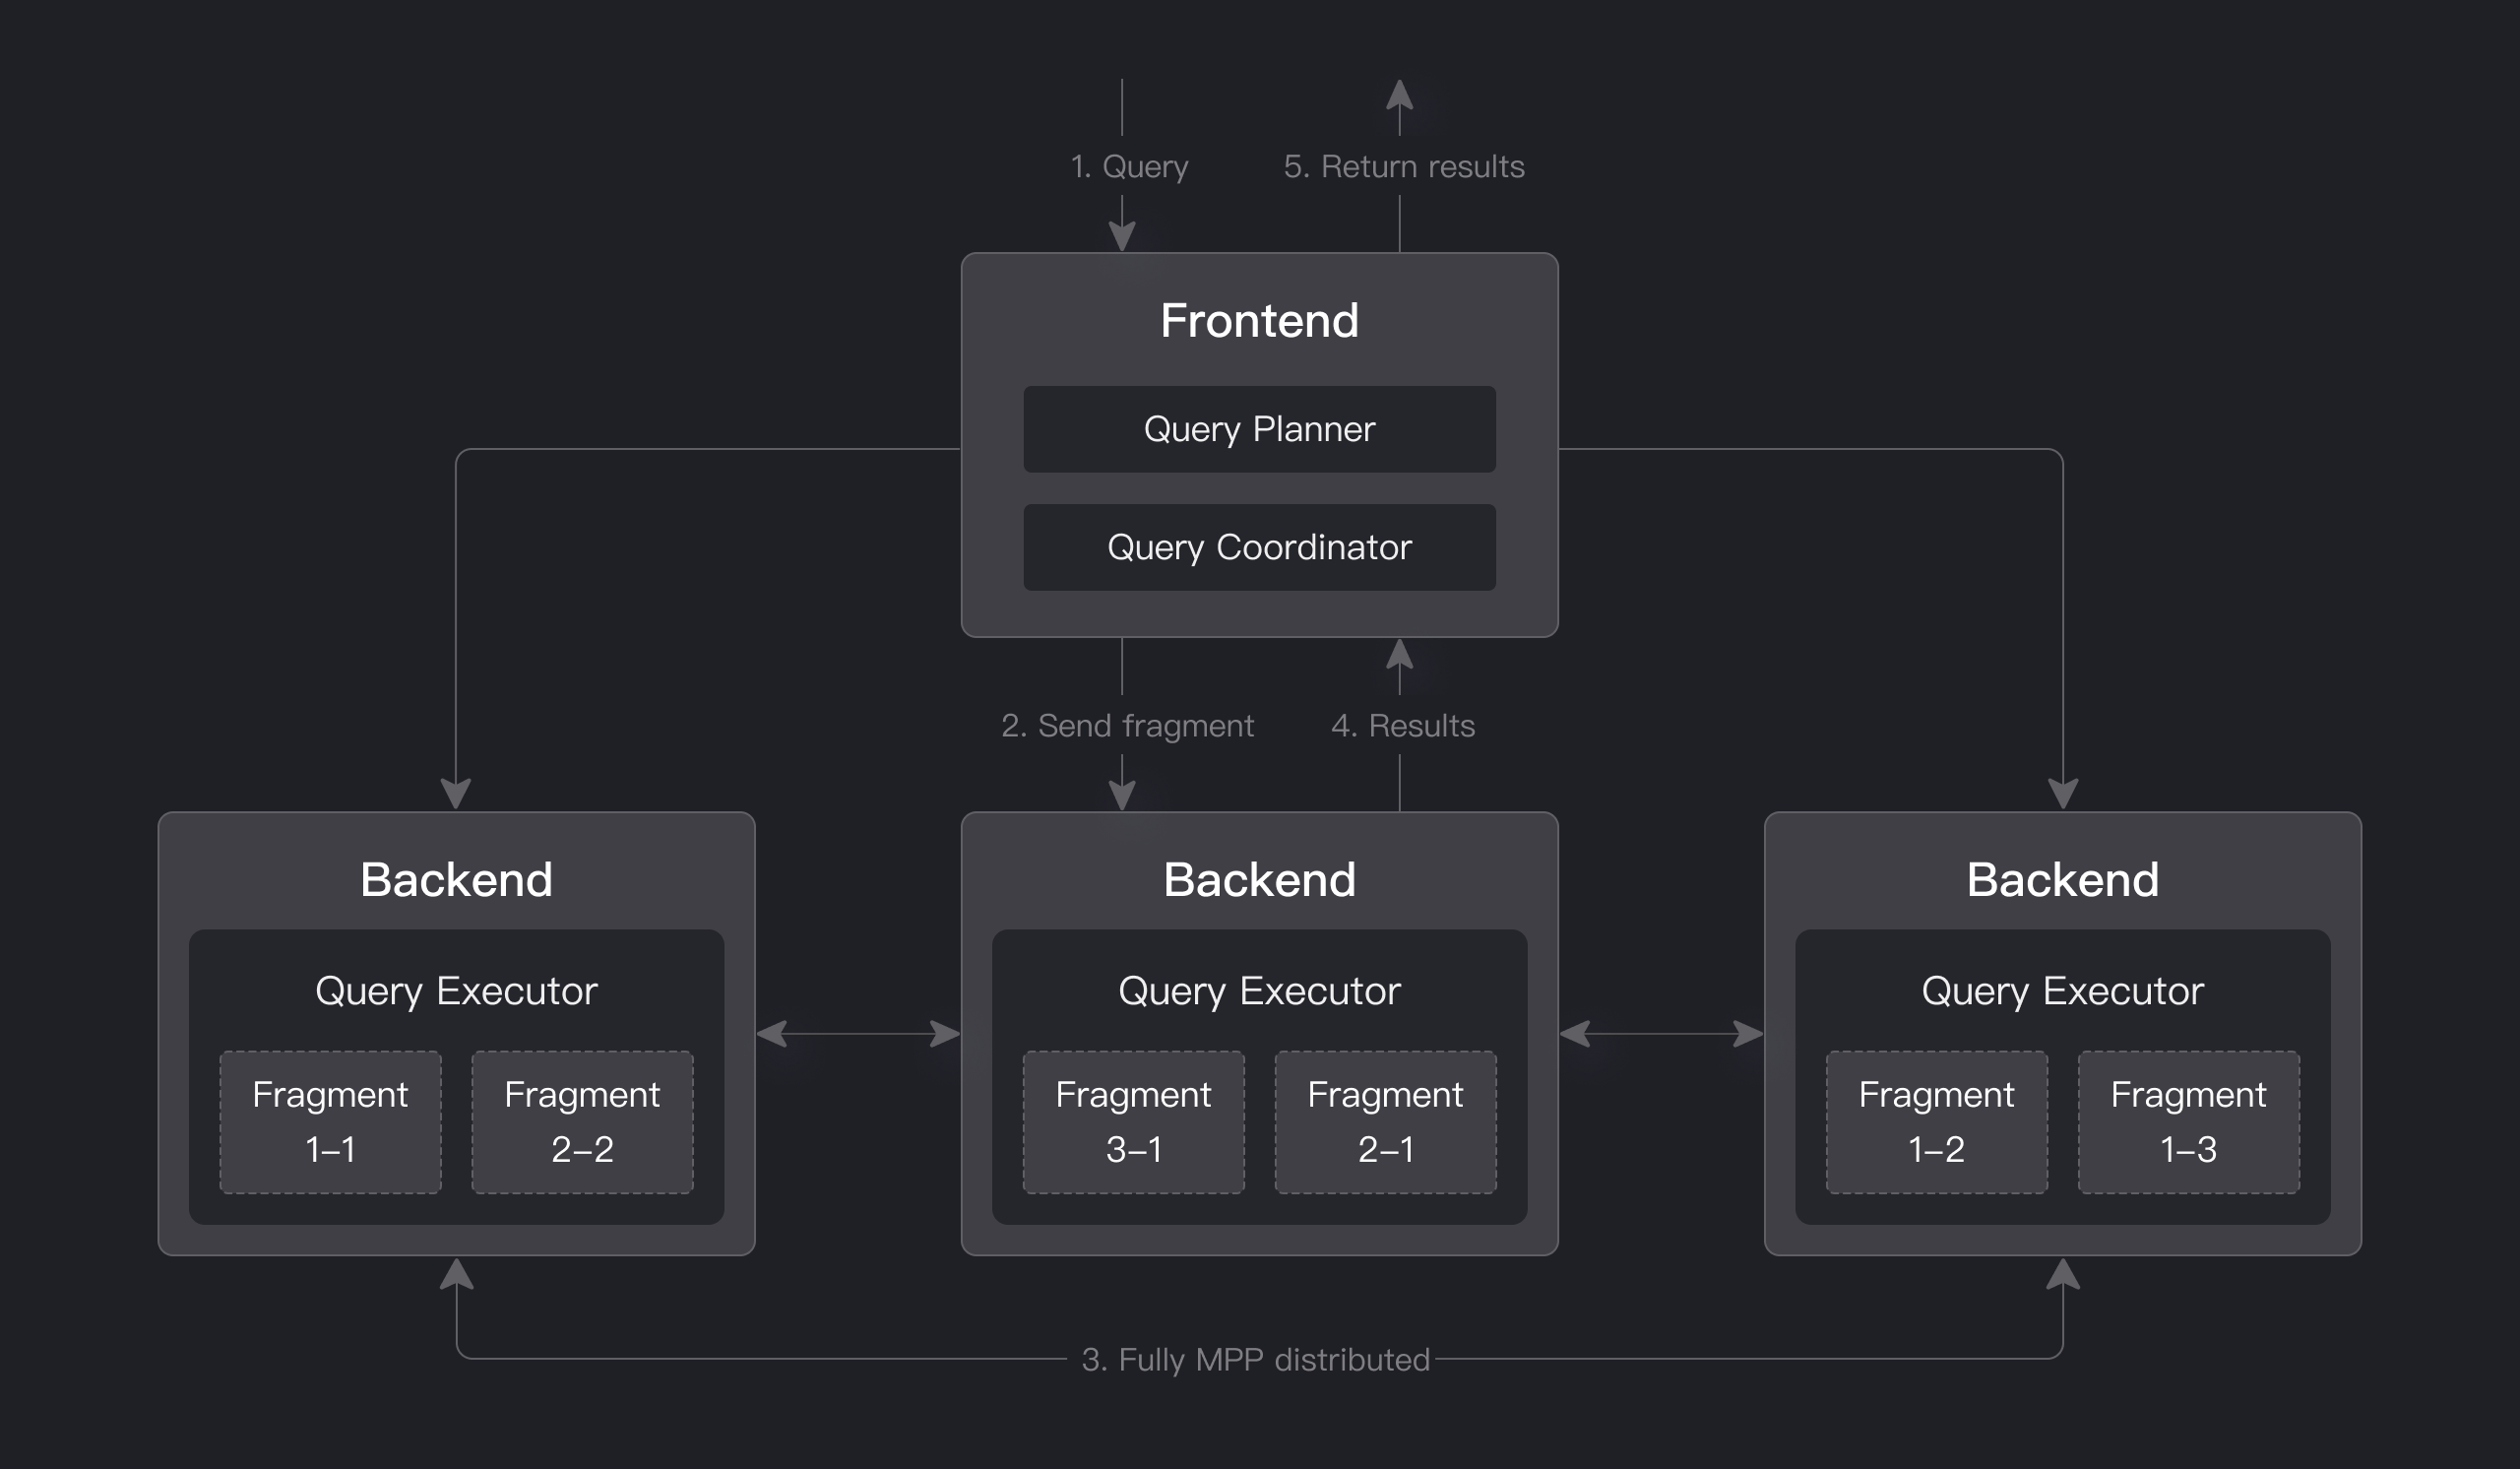
The storage-compute integrated architecture of Apache Doris is streamlined and easy to maintain. As shown in the figure below, it consists of only two types of processes:
-
Frontend (FE): Primarily responsible for handling user requests, query parsing and planning, metadata management, and node management tasks.
-
Backend (BE): Primarily responsible for data storage and query execution. Data is partitioned into shards and stored with multiple replicas across BE nodes.
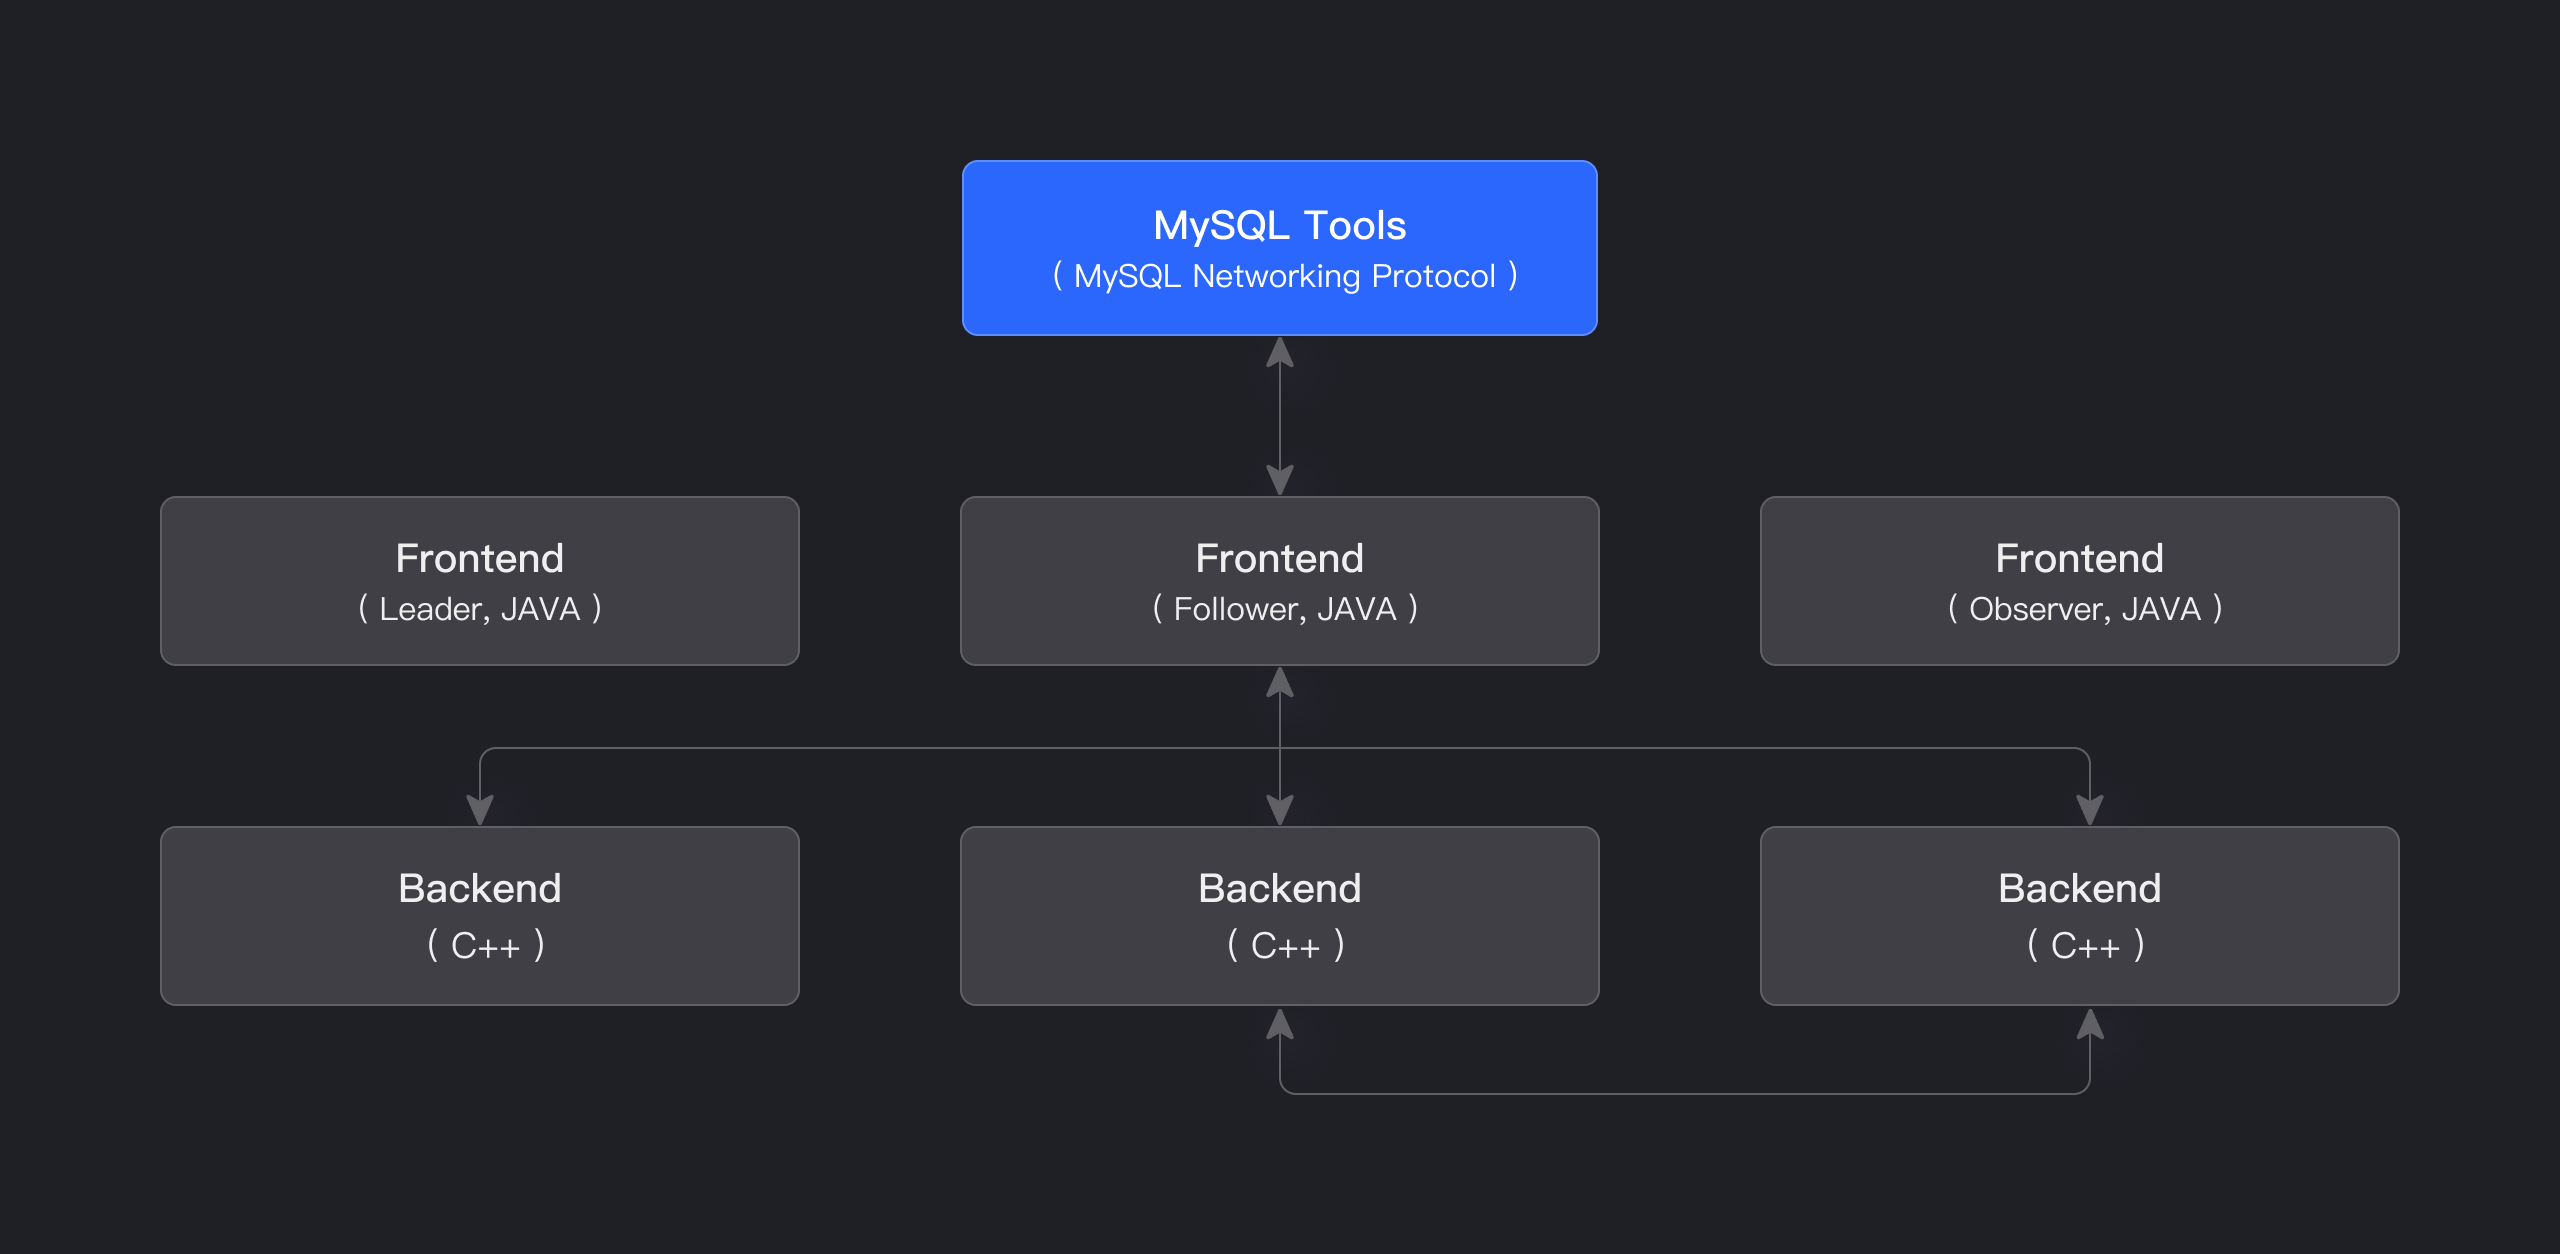
In a production environment, multiple FE nodes can be deployed for disaster recovery. Each FE node maintains a full copy of the metadata. The FE nodes are divided into three roles:
| Role | Function |
|---|---|
| Master | The FE Master node is responsible for metadata read and write operations. When metadata changes occur in the Master, they are synchronized to Follower or Observer nodes via the BDB JE protocol. |
| Follower | The Follower node is responsible for reading metadata. If the Master node fails, a Follower node can be selected as the new Master. |
| Observer | The Observer node is responsible for reading metadata and is mainly used to increase query concurrency. It does not participate in cluster leadership elections. |
Both FE and BE processes are horizontally scalable, enabling a single cluster to support hundreds of machines and tens of petabytes of storage capacity. The FE and BE processes use a consistency protocol to ensure high availability of services and high reliability of data. The storage-compute integrated architecture is highly integrated, significantly reducing the operational complexity of distributed systems.
Core Features of Apache Doris
-
High Availability: In Apache Doris, both metadata and data are stored with multiple replicas, synchronizing data logs via the quorum protocol. Data write is considered successful once a majority of replicas have completed the write, ensuring that the cluster remains available even if a few nodes fail. Apache Doris supports both same-city and cross-region disaster recovery, enabling dual-cluster master-slave modes. When some nodes experience failures, the cluster can automatically isolate the faulty nodes, preventing the overall cluster availability from being affected.
-
High Compatibility: Apache Doris is highly compatible with the MySQL protocol and supports standard SQL syntax, covering most MySQL and Hive functions. This high compatibility allows users to seamlessly migrate and integrate existing applications and tools. Apache Doris supports the MySQL ecosystem, enabling users to connect Doris using MySQL Client tools for more convenient operations and maintenance. It also supports MySQL protocol compatibility for BI reporting tools and data transmission tools, ensuring efficiency and stability in data analysis and data transmission processes.
-
Real-Time Data Warehouse: Based on Apache Doris, a real-time data warehouse service can be built. Apache Doris offers second-level data ingestion capabilities, capturing incremental changes from upstream online transactional databases into Doris within seconds. Leveraging vectorized engines, MPP architecture, and Pipeline execution engines, Doris provides sub-second data query capabilities, thereby constructing a high-performance, low-latency real-time data warehouse platform.
-
Unified Lakehouse: Apache Doris can build a unified lakehouse architecture based on external data sources such as data lakes or relational databases. The Doris unified lakehouse solution enables seamless integration and free data flow between data lakes and data warehouses, helping users directly utilize data warehouse capabilities to solve data analysis problems in data lakes while fully leveraging data lake data management capabilities to enhance data value.
-
Flexible Modeling: Apache Doris offers various modeling approaches, such as wide table models, pre-aggregation models, star/snowflake schemas, etc. During data import, data can be flattened into wide tables and written into Doris through compute engines like Flink or Spark, or data can be directly imported into Doris, performing data modeling operations through views, materialized views, or real-time multi-table joins.
Technical overview
Doris provides an efficient SQL interface and is fully compatible with the MySQL protocol. Its query engine is based on an MPP (Massively Parallel Processing) architecture, capable of efficiently executing complex analytical queries and achieving low-latency real-time queries. Through columnar storage technology for data encoding and compression, it significantly optimizes query performance and storage compression ratio.
Interface
Apache Doris adopts the MySQL protocol, supports standard SQL, and is highly compatible with MySQL syntax. Users can access Apache Doris through various client tools and seamlessly integrate it with BI tools, including but not limited to Smartbi, DataEase, FineBI, Tableau, Power BI, and Apache Superset. Apache Doris can work as the data source for any BI tools that support the MySQL protocol.
Storage engine
Apache Doris has a columnar storage engine, which encodes, compresses, and reads data by column. This enables a very high data compression ratio and largely reduces unnecessary data scanning, thus making more efficient use of IO and CPU resources.
Apache Doris supports various index structures to minimize data scans:
-
Sorted Compound Key Index: Users can specify three columns at most to form a compound sort key. This can effectively prune data to better support highly concurrent reporting scenarios.
-
Min/Max Index: This enables effective data filtering in equivalence and range queries of numeric types.
-
BloomFilter Index: This is very effective in equivalence filtering and pruning of high-cardinality columns.
-
Inverted Index: This enables fast searching for any field.
Apache Doris supports a variety of data models and has optimized them for different scenarios:
-
Detail Model (Duplicate Key Model): A detail data model designed to meet the detailed storage requirements of fact tables.
-
Primary Key Model (Unique Key Model): Ensures unique keys; data with the same key is overwritten, enabling row-level data updates.
-
Aggregate Model (Aggregate Key Model): Merges value columns with the same key, significantly improving performance through pre-aggregation.
Apache Doris also supports strongly consistent single-table materialized views and asynchronously refreshed multi-table materialized views. Single-table materialized views are automatically refreshed and maintained by the system, requiring no manual intervention from users. Multi-table materialized views can be refreshed periodically using in-cluster scheduling or external scheduling tools, reducing the complexity of data modeling.
🔍 Query Engine
Apache Doris has an MPP-based query engine for parallel execution between and within nodes. It supports distributed shuffle join for large tables to better handle complicated queries.
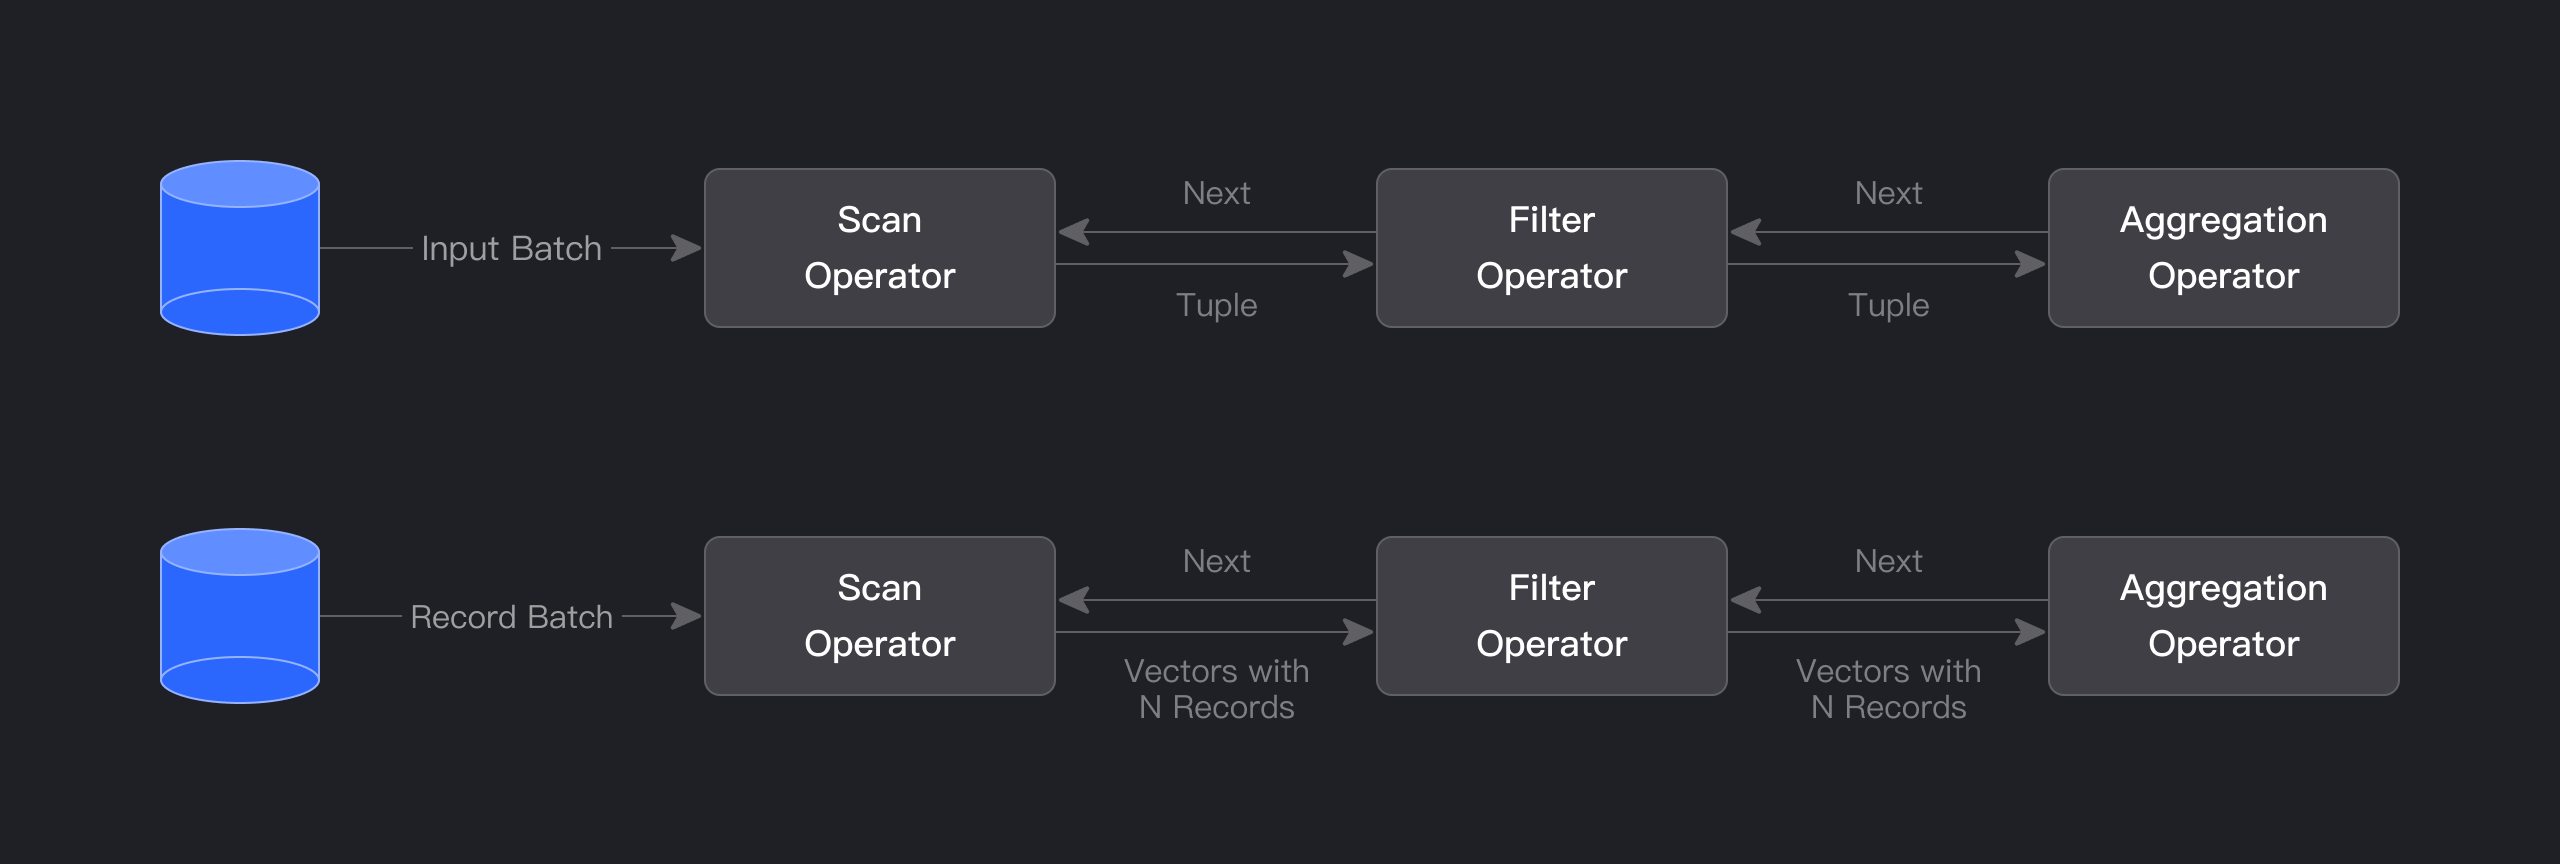
The query engine of Apache Doris is fully vectorized, with all memory structures laid out in a columnar format. This can largely reduce virtual function calls, increase cache hit rates, and make efficient use of SIMD instructions. Apache Doris delivers a 5~10 times higher performance in wide table aggregation scenarios than non-vectorized engines.
Apache Doris uses adaptive query execution technology to dynamically adjust the execution plan based on runtime statistics. For example, it can generate a runtime filter and push it to the probe side. Specifically, it pushes the filters to the lowest-level scan node on the probe side, which largely reduces the data amount to be processed and increases join performance. The runtime filter of Apache Doris supports In/Min/Max/Bloom Filter.
Apache Doris uses a Pipeline execution engine that breaks down queries into multiple sub-tasks for parallel execution, fully leveraging multi-core CPU capabilities. It simultaneously addresses the thread explosion problem by limiting the number of query threads. The Pipeline execution engine reduces data copying and sharing, optimizes sorting and aggregation operations, thereby significantly improving query efficiency and throughput.
In terms of the optimizer, Apache Doris employs a combined optimization strategy of CBO (Cost-Based Optimizer), RBO (Rule-Based Optimizer), and HBO (History-Based Optimizer). RBO supports constant folding, subquery rewriting, predicate pushdown, and more. CBO supports join reordering and other optimizations. HBO recommends the optimal execution plan based on historical query information. These multiple optimization measures ensure that Doris can enumerate high-performance query plans across various types of queries.
🎆 Why choose Apache Doris?
-
🎯 Easy to Use: Two processes, no other dependencies; online cluster scaling, automatic replica recovery; compatible with MySQL protocol, and using standard SQL.
-
🚀 High Performance: Extremely fast performance for low-latency and high-throughput queries with columnar storage engine, modern MPP architecture, vectorized query engine, pre-aggregated materialized view and data index.
-
🖥️ Single Unified: A single system can support real-time data serving, interactive data analysis and offline data processing scenarios.
-
⚛️ Federated Querying: Supports federated querying of data lakes such as Hive, Iceberg, Hudi, and databases such as MySQL and Elasticsearch.
-
⏩ Various Data Import Methods: Supports batch import from HDFS/S3 and stream import from MySQL Binlog/Kafka; supports micro-batch writing through HTTP interface and real-time writing using Insert in JDBC.
-
🚙 Rich Ecology: Spark uses Spark-Doris-Connector to read and write Doris; Flink-Doris-Connector enables Flink CDC to implement exactly-once data writing to Doris; DBT Doris Adapter is provided to transform data in Doris with DBT.
🙌 Contributors
Apache Doris has graduated from Apache incubator successfully and become a Top-Level Project in June 2022.
We deeply appreciate 🔗community contributors for their contribution to Apache Doris.
👨👩👧👦 Users
Apache Doris now has a wide user base in China and around the world, and as of today, Apache Doris is used in production environments in thousands of companies worldwide. More than 80% of the top 50 Internet companies in China in terms of market capitalization or valuation have been using Apache Doris for a long time, including Baidu, Meituan, Xiaomi, Jingdong, Bytedance, Tencent, NetEase, Kwai, Sina, 360, Mihoyo, and Ke Holdings. It is also widely used in some traditional industries such as finance, energy, manufacturing, and telecommunications.
The users of Apache Doris: 🔗Users
Add your company logo at Apache Doris Website: 🔗Add Your Company
👣 Get Started
📚 Docs
All Documentation 🔗Docs
⬇️ Download
All release and binary version 🔗Download
🗄️ Compile
See how to compile 🔗Compilation)
📮 Install
See how to install and deploy 🔗Installation and deployment
🧩 Components
📝 Doris Connector
Doris provides support for Spark/Flink to read data stored in Doris through Connector, and also supports to write data to Doris through Connector.
🌈 Community and Support
📤 Subscribe Mailing Lists
Mail List is the most recognized form of communication in Apache community. See how to 🔗Subscribe Mailing Lists
🙋 Report Issues or Submit Pull Request
If you meet any questions, feel free to file a 🔗GitHub Issue or post it in 🔗GitHub Discussion and fix it by submitting a 🔗Pull Request
🍻 How to Contribute
We welcome your suggestions, comments (including criticisms), comments and contributions. See 🔗How to Contribute and 🔗Code Submission Guide
⌨️ Doris Improvement Proposals (DSIP)
🔗Doris Improvement Proposal (DSIP) can be thought of as A Collection of Design Documents for all Major Feature Updates or Improvements.
🔑 Backend C++ Coding Specification
🔗 Backend C++ Coding Specification should be strictly followed, which will help us achieve better code quality.
💬 Contact Us
Contact us through the following mailing list.
| Name | Scope | |||
|---|---|---|---|---|
| dev@doris.apache.org | Development-related discussions | Subscribe | Unsubscribe | Archives |
🧰 Links
- Apache Doris Official Website - Site
- Developer Mailing list - dev@doris.apache.org. Mail to dev-subscribe@doris.apache.org, follow the reply to subscribe the mail list.
- Slack channel - Join the Slack
- Twitter - Follow @doris_apache
📜 License
Note
Some licenses of the third-party dependencies are not compatible with Apache 2.0 License. So you need to disable some Doris features to be complied with Apache 2.0 License. For details, refer to the
thirdparty/LICENSE.txt